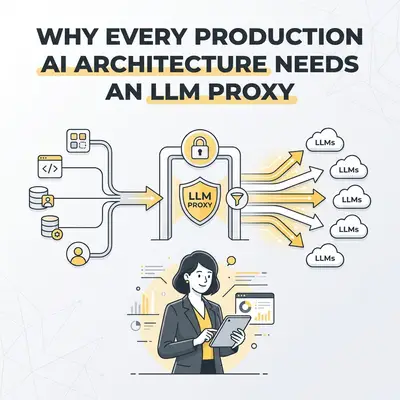
An LLM proxy is a gateway server that sits between your application code and your model providers. Your apps call one endpoint, and the proxy forwards each request to OpenAI, Anthropic, Google or another provider.
Many teams start by wiring a provider API key straight into their code. That works for a prototype. In production, it leaves key management, retries, cost tracking and logging scattered across every service. A proxy moves those jobs into one layer you can control.
What Is an LLM Proxy?
An LLM proxy is an API gateway built for model traffic. The LiteLLM project describes its proxy as a self-hosted server that offers "one OpenAI-compatible endpoint for 100+ LLM providers." Existing OpenAI-client code can point at it without changes.
The proxy handles routing, authorization, logging and spend tracking before it forwards the request. To your services, it looks like one stable API. To the providers, it looks like a normal API client.
Managed options exist too. Cloudflare's AI Gateway is a hosted service that adds analytics, logging, caching, rate limiting, and request retry and fallback to AI applications.
LLM Proxy vs Direct API Calls
The table compares the two setups on the jobs that matter in production. Features vary by product, so check your chosen tool's docs.
| Concern | Direct provider API calls | Via an LLM proxy |
|---|---|---|
| Retries and fallback | Written and maintained in each service | Configured once; for example LiteLLM supports num_retries and ordered fallbacks |
| Cost tracking | Separate dashboard per provider | Spend recorded per key, team, user or tag in one place |
| Rate limits | Only the provider's limits | Your own per-key limits, such as requests or tokens per minute |
| Key management | Provider keys copied into repos and machines | Virtual keys for services; provider keys stay in the proxy |
| Logging | Whatever each service logs itself | Central request and error logs, often exportable to tools like Langfuse or Datadog |
| Switching providers | Code changes in each service | Change the mapping in the proxy |
| Operational cost | None extra | One more component to run, secure and keep available |
Why Provider Dashboards Are Not Enough
Provider dashboards show what one account spent with one vendor. They are not built around your internal structure. Splitting usage by internal tenant, feature or environment usually means tagging requests yourself.
If you use more than one provider, you also compare usage across several portals with different formats. A proxy records every request in one schema, so you can slice by the fields you care about.
What Problems Does an LLM Proxy Solve?
Centralized Key Management and Security
Copying provider keys across repos and developer machines widens your exposure. With a proxy, you issue virtual keys to services and developers instead.
LiteLLM's docs describe virtual keys that can be limited to specific models, given budgets and rate limits, blocked, and set to expire. The master provider keys stay in the proxy environment.
Spend Tracking and Rate Limits
A proxy can record the cost of each request and attribute it to a key, user, team or tag. You can then set a max_budget per key and cap requests or tokens per minute.
This helps you catch a runaway agent loop through a budget cap rather than a surprise invoice. It does not change what the provider charges.
Retries and Multi-Provider Fallbacks
Model APIs hit rate limits and errors. Without a proxy, each service needs its own retry and failover code.
In LiteLLM, you set the retry count first, then an ordered list of fallback models. If a call fails after its retries, the proxy tries the next model group. Cloudflare AI Gateway lists retry and fallback among its features as well.
[Application Code]
       |
       v
[LLM Proxy]
       |-- Primary: Provider A model
       '-- Fallback: Provider B model
Pro Tip: Fallback models can differ in quality, context size and price. Test the fallback path with your real prompts before you rely on it.
Logging and a Stable Endpoint
Central logs let you see the payload, latency and errors for any request. Be careful here: prompts often contain personal or confidential data, so decide what you store and for how long.
A stable endpoint also helps with change. Models and versions move quickly. With a proxy, you change the model mapping in one config instead of editing every microservice.
How Do You Roll Out an LLM Proxy?
You do not need to build a gateway from scratch. Start with an existing tool and test it in staging.
- Pick a tool: Compare a self-hosted option such as LiteLLM with a managed gateway such as Cloudflare AI Gateway.
- Deploy it: For self-hosting, run it in your own cloud or VPC, for example with Docker or Kubernetes.
- Move provider keys: Store them in the proxy environment, not in app repos.
- Issue virtual keys: Create one per service or environment, with budgets and model limits.
- Change the base URL: Point your SDK or HTTP client at the proxy instead of the provider.
- Turn on logging: Send logs and metrics to the monitoring stack you already use.
Trade-Offs to Weigh
A proxy is also a new point of failure. If it goes down, every AI call goes down with it, so plan for high availability. It adds a network hop, and a self-hosted one adds patching and security work.
For a single small app with one provider, direct calls may be enough. A proxy pays off as the number of services, providers and users grows. If cost is your main concern, start with our guide to calculating token costs for an AI project.
Sources
- LiteLLM AI Gateway (proxy) documentation
- LiteLLM: Virtual keys
- LiteLLM: Reliability, retries and fallbacks
- Cloudflare AI Gateway documentation